VFlash: Fast, Accurate Visual Planning via Flash Primitive Decoding
u_Unrolled
D22: AI System Design Bank · Case Study: Prefix Caching KV Store — Block Keys, Prefix-Aware Routing and Memory Tiers at Staff Level
Phase 9/Domain 22/Lesson 47

Case Study: Prefix Caching KV Store — Block Keys, Prefix-Aware Routing and Memory Tiers at Staff Level

35 min read·Staff+ Tier· Unrolled Pro
Case Study: Prefix Caching KV Store — Block Keys, Prefix-Aware Routing and Memory Tiers at Staff Level

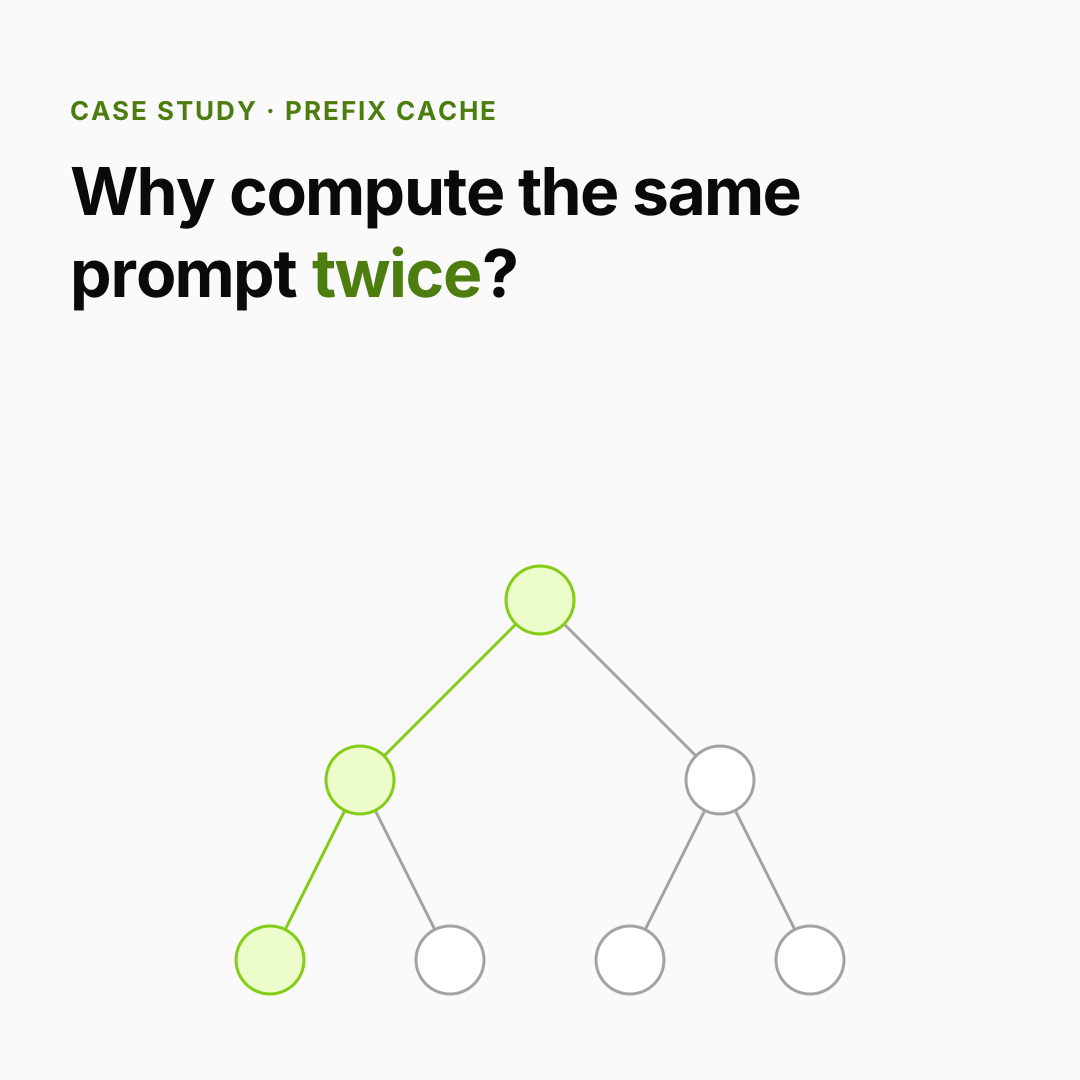
You already know: LLM serving (prefill, decode, the KV cache), the LLM gateway and multi-tenant LoRA serving. This case adds reuse of the prefill work across requests. When a model reads a prompt (the prefill), it produces a key and value vector for every token in every layer: the KV cache. If the next request starts with exactly the same tokens, those vectors are identical and can be reused instead of recomputed. The design questions: how to key the cache so reuse is exact, how to route requests to where their prefix lives, which memory tier is worth using, and who is allowed to share what.

How to read this lesson. No code, on purpose. Numbers marked assumed are assumptions you state out loud.


1. The prompt, and the questions that change the design

A mid-level answer: "put a cache in front of the model, keyed by the prompt". A staff candidate notices three things. First, the cache stores intermediate model state, not answers, so the request still runs; only the prefill of the shared part is skipped. Second, reuse is only valid when every earlier token is identical, which makes prompt layout and keys the centre of the design. Third, the cache lives on the GPU nodes themselves, so routing decides the hit rate: a perfect cache on the wrong machine is worth nothing.

Assumptions you state:

That's the preview. The full lesson, with its code and exercises, is part of Unrolled Pro.
Staff AI & Pro Tier Lesson

Unlock "Case Study: Prefix Caching KV Store — Block Keys, Prefix-Aware Routing and Memory Tiers at Staff Level"

The foundations are free forever. Unrolled Pro unlocks the complete lesson, production architectures, and 55 battle-tested ML system design case studies.

Everything included with Pro:
All 234+ Deep-Dive Lessons across transformer internals, inference, RAG & agents
55 Staff-Level ML & System Design Case Studies with mathematical capacity estimates
AI Engineer Sheet & Exercises with worked solutions, self-checks, and code
100 Landmark Research Papers guided walkthroughs & progress tracking
14-Day Money-Back Guarantee — 100% full refund if you aren't satisfied
View Plans & Unlock All Lessons

From ₹167/mo (~$2/mo) · Cancel anytime · Instant activation

100% Risk-Free: 14-day no-questions-asked money-back guarantee