From zero toStaff AI engineer.Every step, mapped.
Never trained a model? Start here. One road takes you from how Python runs your code to training, fine-tuning and grounding your own GPT: the skills AI engineering roles ask for, built from first principles.
239 lessons · 928 tested code examples · foundations free, no card
Pick a path
Learn for a specific role
Prefer a goal-based route? Each path is the same lessons, ordered around the role you want.
1. Where are you today?
2. Where do you want to be?
01 · 3 paths
Foundations
Start here if you are new to coding, data or the maths.
Python: Basics to Advanced
- 1Thinking in Python
- 2Data structures
- 3Under the hood
- +4 more stages
Mastering SQL
- 1Querying
- 2Analysis
- 3The engine
- +1 more stages
Maths for Machine Learning
- 1Reading the language
- 2Linear algebra
- 3Calculus
- +2 more stages
02 · 3 paths
Machine learning core
How models learn, from classic ML to deep learning and vision.
Machine Learning
- 1Part 1: Data as tensors
- 2Part 2: Learning from data
- 3Classical ML in depth
- +1 more stages
Deep Learning
- 1Part 3: Neural networks from scratch
- 2Architectures beyond transformers
- 3Part 4: From text to GPT
- +2 more stages
Computer Vision
- 1Part 3: Neural networks from scratch
- 2Architectures beyond transformers
- 3Vision and multimodal AI
03 · 3 paths
LLMs and frontier AI
What frontier labs build: LLMs, RL and research.
LLMs in Depth
- 1Part 3: Neural networks from scratch
- 2Part 4: From text to GPT
- 3Part 5: Make it helpful
- +5 more stages
Reinforcement Learning
- 1Probability first
- 2Reinforcement learning
- 3RL for language models
AI Research
- 1Research maths
- 2Part 3: Neural networks from scratch
- 3Part 4: From text to GPT
- +3 more stages
04 · 5 paths
Build and ship AI
Put AI into products and keep it fast, reliable and cheap.
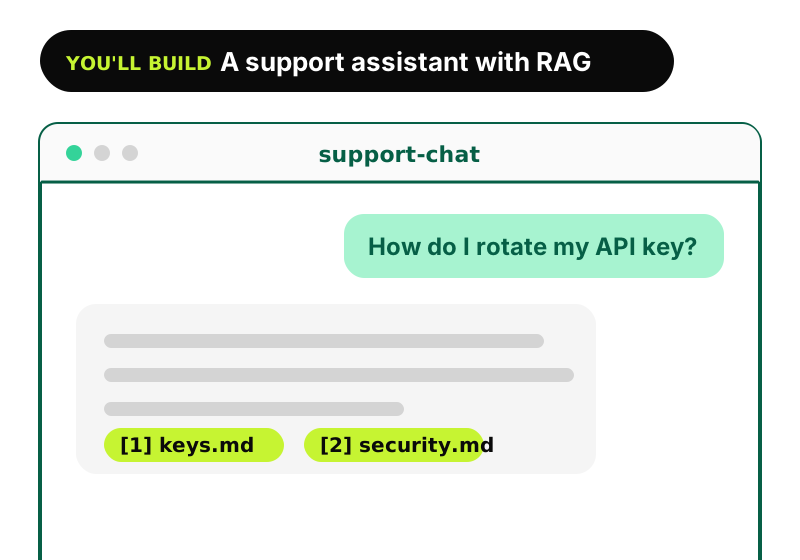
AI Engineering
- 1Part 6: Talk to it well
- 2Part 7: Ground it in your documents
- 3Part 8: Let it act
- +3 more stages
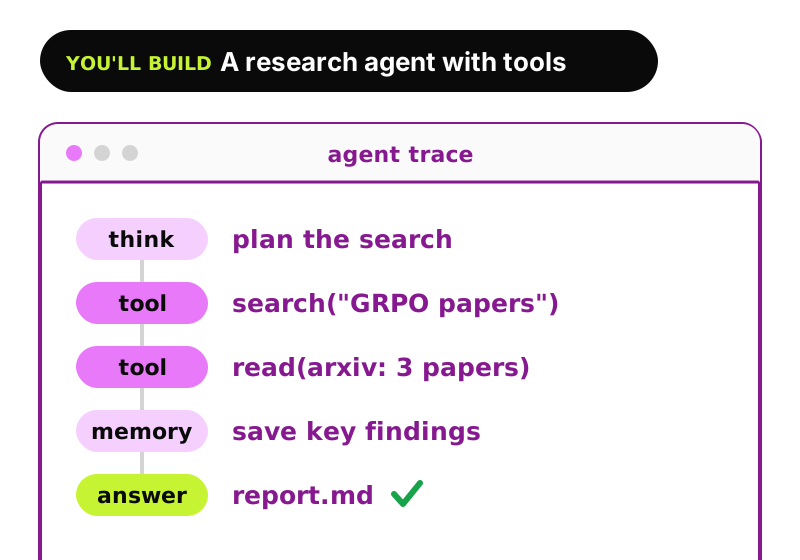
Agentic AI
- 1Part 6: Talk to it well
- 2Part 8: Let it act
- 3Evaluation engineering
- +1 more stages
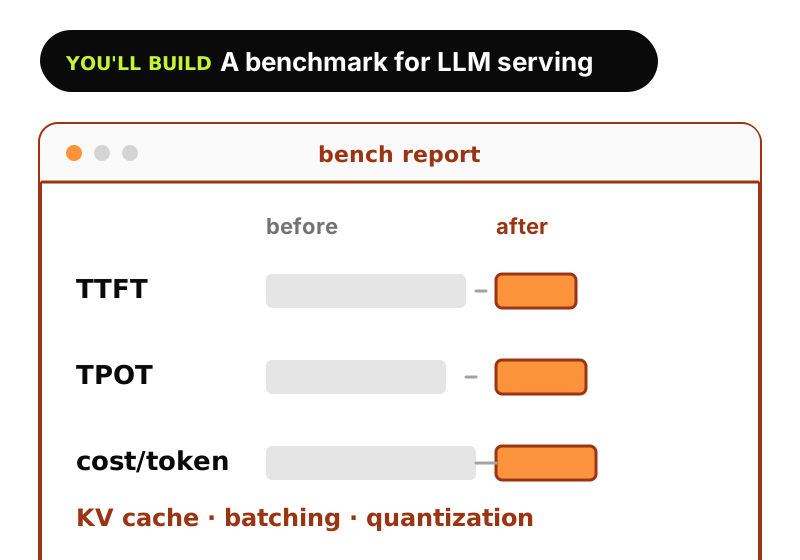
Inference Engineering
- 1What you are serving
- 2Systems underneath
- 3Part 9: Serve it fast
- +2 more stages
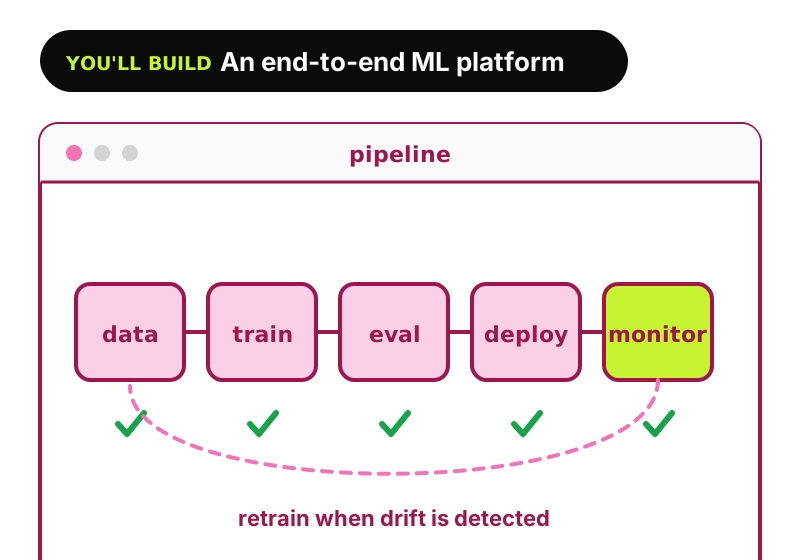
MLOps & Production ML
- 1Data and models in production
- 2MLOps
- 3Cloud and platform engineering
- +2 more stages
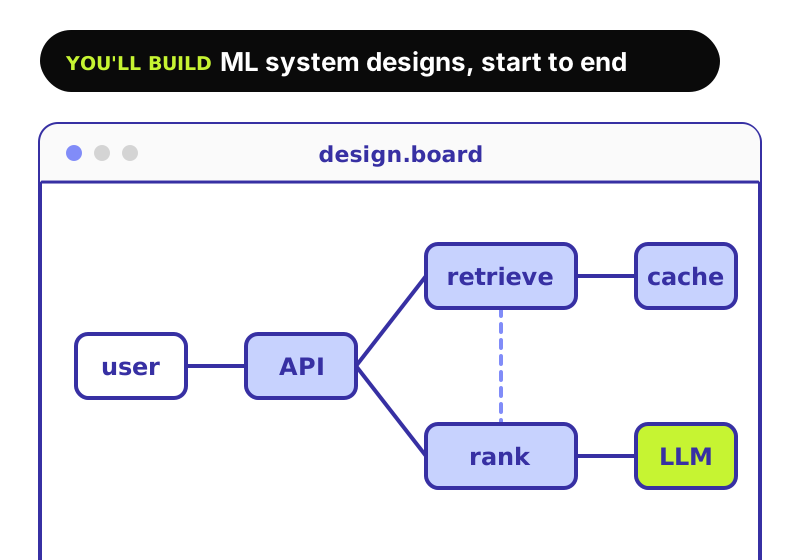
ML & AI System Design
- 1Building blocks
- 2Distributed systems
- 3AI & ML system design bank
- +1 more stages
Looking for one topic? Search the Library
Or build one project · Build Atlas
One road. One project.
Nine parts, in order. Each adds a working piece to Atlas, an AI assistant you build from scratch.
- 1Data as tensorsLoad and shape data, and do the maths on whole arrays3 lessons
- 2Learning from dataA baseline model, and an evaluation you can trust3 lessons
- 3Neural networks from scratchYour own training loop, gradients included4 lessons
- 4From text to GPTTinyGPT: a small language model you train yourself7 lessons
- 5Make it helpfulA chat model: fine-tuned, aligned and cheaper to adapt5 lessons
- 6Talk to it wellPrompts, context and evaluations for Atlas4 lessons
- 7Ground it in your documentsRetrieval-augmented answers with citations7 lessons
- 8Let it actAtlas as an agent: tools, memory and safe actions10 lessons
- 9Serve it fastBatching, KV cache and cost per token16 lessons
Beyond the courses
Everything else we offer.
Show, don't tell
Real code. Real output.
Every example in every lesson is run before it's published, and the numbers in the text are the numbers it prints. No pseudo-code, no “left as an exercise”.
Fine-tune an 8B model by training half a percent of it.
d, ffn, kv, r = 4096, 14336, 1024, 16  # Llama-3-8B
shapes = [(d, d), (d, kv), (d, kv), (d, d),
          (d, ffn), (d, ffn), (ffn, d)]
lora = 32 * sum(r * (i + o) for i, o in shapes)
share = lora / 8.03e9
print(f"trains {lora/1e6:.0f}M of 8,030M = {share:.2%}")trains 42M of 8,030M = 0.52%
Why a single modest GPU can customise a large model.
Inside a lesson
Question. Build. Prove it.
A real section from Build an LLM from Scratch.
What should the loss be at step 0, and why does it matter?
An untrained model should spread its bets evenly over the vocabulary, so the starting loss should be ln V. If it's far higher, the model starts confidently wrong.
for std in [1.0, 0.02]:
    emb = torch.randn(V, d) * std
    logits = emb[tokens] @ emb.T
    loss = F.cross_entropy(logits.view(-1, V),
                           targets.view(-1))
    print(f"init std {std}: starting loss "
          f"{loss:.2f} | ln(V) = {math.log(V):.2f}")
init std 1.0: starting loss 128.26 | ln(V) = 4.53 init std 0.02: starting loss 4.53 | ln(V) = 4.53
Write overfit_one_batch(model, x, y).
A healthy model must memorize a single batch. If it can't, the plumbing is broken. The worked solution drives the loss from 3.90 to 0.003.
Open this lessonBuilt from first principles by AI engineers · About the platform
Plans
Start free. Go Pro when you're hooked.
The foundations are free forever, no card. Pro unlocks every other lesson, plus each new lesson as it's published.
- 49 lessons: Domain 1 and the first 3 of every path
- Build Atlas Parts 1–2
- Easy practice problems and the first 10 papers of the 100-day challenge
- Weekly challenges, tools and community
- No card, no sign-up to read
- Every lesson, all of Build Atlas, every practice problem and all 100 papers
- 55 Staff-Level ML & System Design Case Studies
- Runnable code and worked solutions
- 14-day refund guarantee · Cancel anytime
- Every lesson, all of Build Atlas, every practice problem and all 100 papers
- 55 Staff-Level ML & System Design Case Studies
- Runnable code and worked solutions
- 14-day refund guarantee · Cancel anytime
- Every lesson, all of Build Atlas, every practice problem and all 100 papers
- 55 Staff-Level ML & System Design Case Studies
- Runnable code and worked solutions
- 14-day refund guarantee · Cancel anytime
Secure payments by Razorpay · prices in INR, GST included where applicable · plan details
FAQ
Questions before you start
Who is this for?
Software engineers who want to understand and build AI systems, not just call an API. You should be comfortable programming; Domain 1 starts from how Python actually runs your code, so no ML background is needed.
Do I need a GPU?
No. Every code example runs on an ordinary laptop CPU in seconds to a couple of minutes. Lessons explain where GPUs change the picture.
How long does a lesson take?
Most lessons are a 10–25 minute read, plus time for the self-check questions and the exercise. Work through them in order: each lesson lists what it builds on.
What is free?
All of the foundations: the full Python track plus the CS and systems lessons, with no card and no sign-in required to read. Unrolled Pro unlocks everything after them, including the rest of Build Atlas.
Is the curriculum finished?
Not yet: 239 lessons are written, covering the foundations and Parts 1–7 of Build Atlas. Agents and serving (Parts 8 and 9) are being written now. Pro includes every new lesson as it is published, at no extra cost.
Can I cancel?
Yes, anytime directly with one click and your plan won't renew. You keep access until the end of the period you've paid for.
Pick a path. Start free.
One road from arrays of numbers to a GPT you train, fine-tune and ground in documents, plus paths for specific goals. Python and the foundations are free, with no card.