This page builds the code. The ideas behind it are taught in the Library lessons listed at the end; read them first if a step uses something you haven't met. Inspect and copy the complete code in the Atlas Codebase Browser and run each step as you read.
Part 2's model learned with a gradient we derived by hand. That stops working the moment the model gets a second layer. This part builds the machine that derives gradients for you, a small automatic-differentiation engine of about 100 lines, and checks it against brute-force numerical derivatives. Then it switches to PyTorch, which does the same thing on tensors, and writes the training loop Atlas will reuse for its GPT.
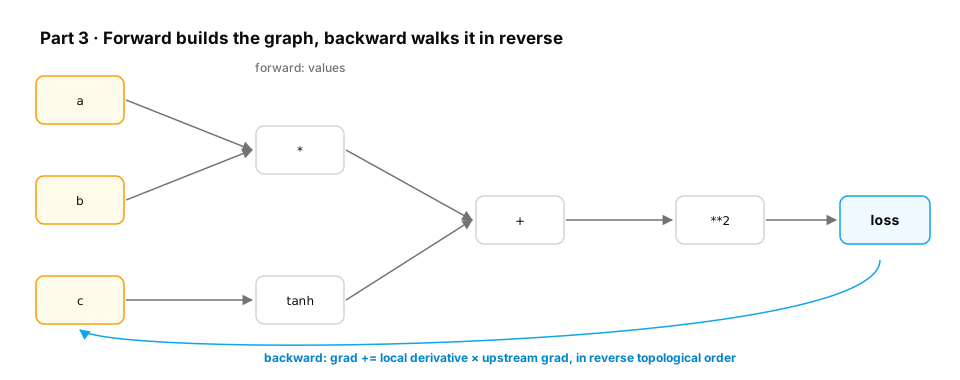
Diagram— a computation graph runs forward from inputs to a loss; backward walks the same graph in reverse, multiplying local derivatives into each input's gradient.
Step 1 · A number that remembers where it came from
Every Value stores its data, its gradient, the values it was made from, and a small function that knows the local derivative of the operation that made it. Multiplication is the whole idea in miniature: the derivative of a * b with respect to a is b.
The += matters: a value used twice (like a in a * b + a) collects gradient from both uses.
That's the preview. Build Atlas Parts 1 and 2 are free; the full walkthrough of Part 3 is part of Unrolled Pro.
Staff AI & Pro Tier Lesson
Unlock "Build Atlas, Part 3: Neural networks from scratch"
The foundations are free forever. Unrolled Pro unlocks the complete lesson, production architectures, and 55 battle-tested ML system design case studies.
Everything included with Pro:
All 234+ Deep-Dive Lessons across transformer internals, inference, RAG & agents
55 Staff-Level ML & System Design Case Studies with mathematical capacity estimates
AI Engineer Sheet & Exercises with worked solutions, self-checks, and code
100 Landmark Research Papers guided walkthroughs & progress tracking
14-Day Money-Back Guarantee — 100% full refund if you aren't satisfied